Posts tagged文章分類

Gen AI生成式 AI

Evaluation, retrieval, agents, and cost control.評估、檢索、代理系統與成本控制。

From RAG Prototype to Deployment Decision: A CFPB Case Study
Gen AI生成式 AI15 Jul 20262026年7月15日

From RAG Prototype to Deployment Decision: A CFPB Case Study從 RAG 原型到部署決策:CFPB 案例研究

A practical guide to designing and evaluating RAG through a LangChain complaint-triage case study—and deciding why the prototype is suitable for a controlled analyst-assistance pilot, but not autonomous deployment.本文透過一個以 LangChain 建構的申訴分流案例,說明如何設計與評估 RAG 系統,以及為何這項原型適合進入受控的分析師輔助試點,卻尚不足以支援自主部署。

38 min read閱讀約 66 分鐘
LLM Fine-Tuning: Teaching a Small Model to Analyze 10-K Risk Disclosures
Gen AI生成式 AI1 Jul 20262026年7月1日

LLM Fine-Tuning: Teaching a Small Model to Analyze 10-K Risk DisclosuresLLM 微調實務:以小型模型分析 10-K 風險揭露

A practical guide to supervised fine-tuning, PEFT, LoRA, and QLoRA—covering dataset design, loss masking, leakage-resistant evaluation, and a hands-on experiment with SEC 10-K risk disclosures.從監督式微調、PEFT、LoRA 與 QLoRA 出發,說明資料集設計、損失遮罩與防止資料外洩的評估方法,並以 SEC 10-K 風險揭露進行實驗。

23 min read閱讀約 40 分鐘

LLM Serving: Continuous Batching, Distributed Execution, and Service-Level Objectives
Gen AI生成式 AI26 Jun 20262026年6月26日

LLM Serving: Continuous Batching, Distributed Execution, and Service-Level ObjectivesLLM 正式環境部署:批次處理、分散式推論與服務等級目標

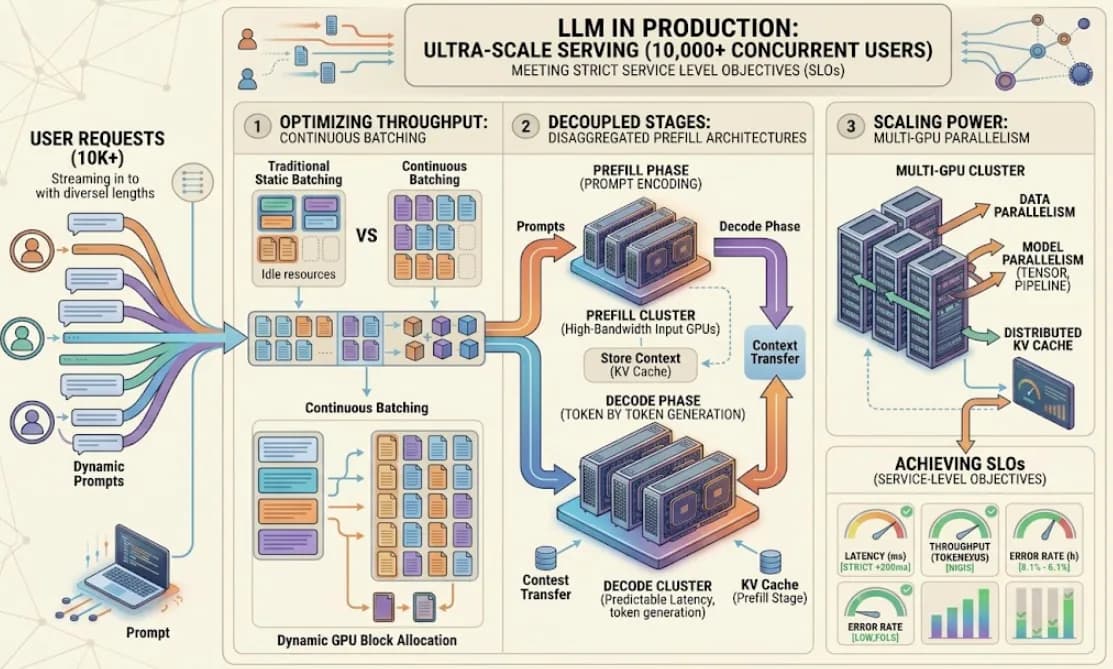
How do you serve 10,000 concurrent users? A deep dive into continuous batching, disaggregated prefill architectures, and multi-GPU parallelism to meet strict Service-Level Objectives in production, plus a troubleshooting quick-reference.深入解析連續批次處理、分離式預填充、多 GPU 平行化與 SLO,說明如何將模型檢查點轉化為可擴展、可監控的正式服務。

16 min read閱讀約 22 分鐘

LLM Inference: How KV Caching and PagedAttention Save LLM Inference
Gen AI生成式 AI25 Jun 20262026年6月25日

LLM Inference: How KV Caching and PagedAttention Save LLM InferenceLLM 推論:KV 快取、FlashAttention 與 PagedAttention

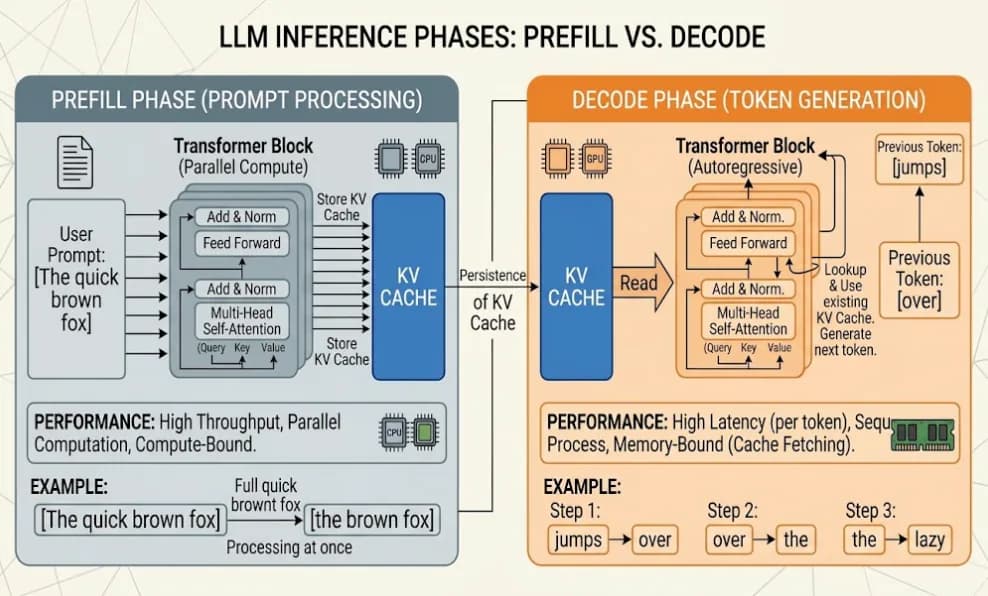
When models scale, memory becomes the enemy. A deep dive into the engineering behind prefill and decode bottlenecks, and the memory management breakthroughs that make real-time generative serving feasible.解析預填充與解碼的不同瓶頸,以及 KV 快取、FlashAttention、PagedAttention 與模型壓縮如何改善 LLM 推論效率。

19 min read閱讀約 29 分鐘

LLM Pretrain: Anatomy of a Decoder-Only Transformer
Gen AI生成式 AI20 Jun 20262026年6月20日

LLM Pretrain: Anatomy of a Decoder-Only TransformerLLM 預訓練:深入解析純解碼器 Transformer

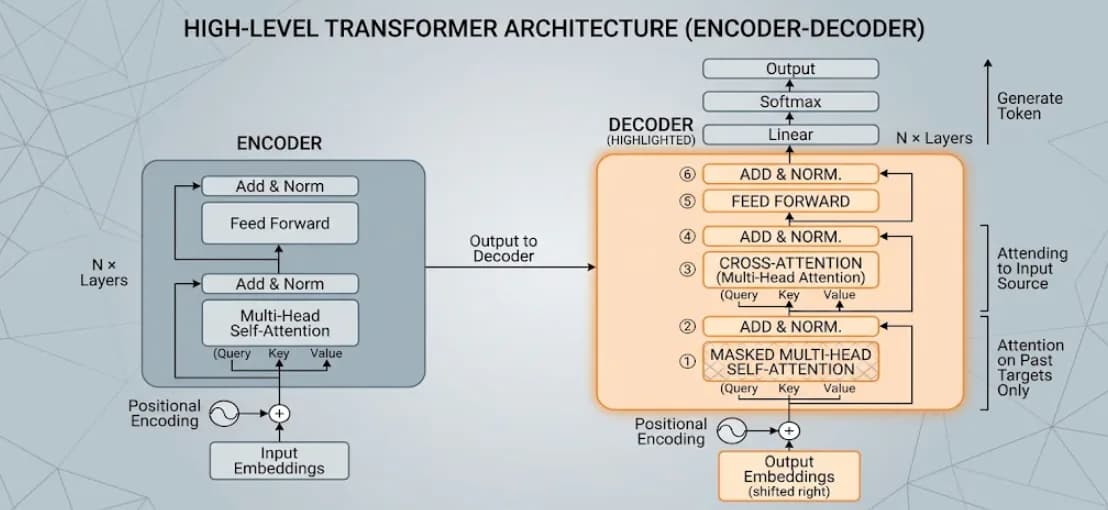
A rigorous, step-by-step breakdown of the LLM generation engine. Unpack the exact mechanics of RoPE, causal self-attention, and grouped-query attention to see how a prompt becomes a prediction.從 tokenization、RoPE、因果自注意力到閘控前饋網路,逐步解析提示詞如何轉換為下一個 token 的機率分布。

16 min read閱讀約 25 分鐘

How We Got to LLMs: From Word2Vec to the Transformer
Gen AI生成式 AI15 Jun 20262026年6月15日

How We Got to LLMs: From Word2Vec to the Transformer大型語言模型如何演進:從 Word2Vec 到 Transformer

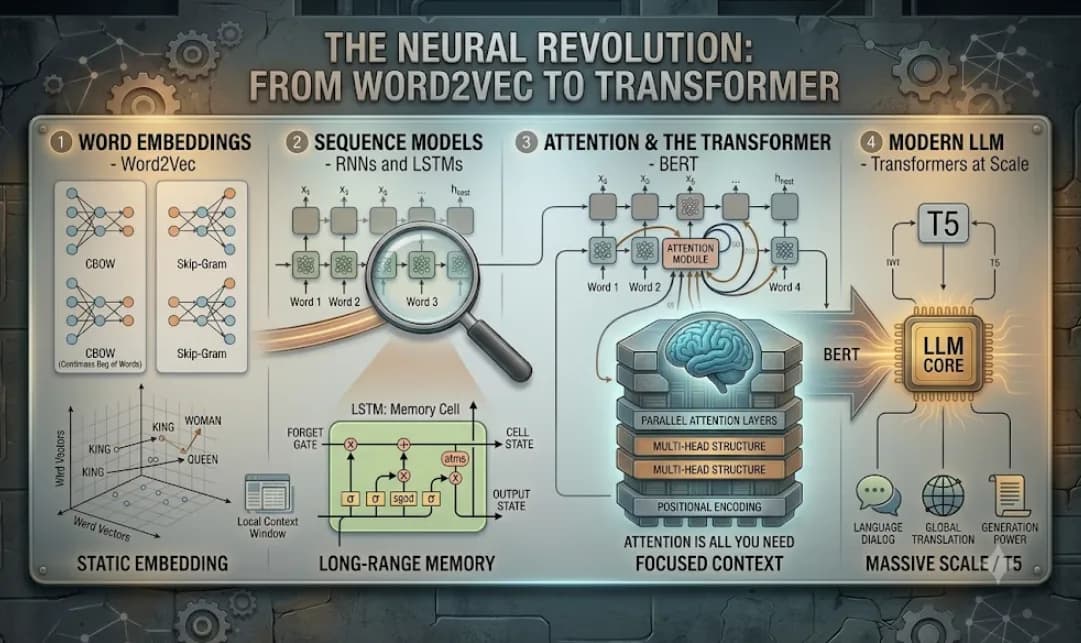
Four architectural leaps—word embeddings, RNNs, the Transformer, and scale—each one a fix for the last one's limit, and the reason today's LLMs are capable, confident, and occasionally wrong.從詞嵌入、RNN 到 Transformer 與規模化,四次關鍵的技術躍進如何突破前一階段的限制,並塑造今日 LLM 的能力與局限。

25 min read閱讀約 46 分鐘